I've always believed coding to be a creative endeavor, but it came with a unique kind of infuriating tedium. Today I recall, with a strange mix of nostalgia and trauma, the times in undergrad when I spent hours banging my head against a missing semi-colon. Or coding at 1stdibs.com and putting print() statements at the top of every function to figure out where my data was being dropped. Or three days of endlessly reading StackOverflow(RIP) threads to try and get out of dependency hell after I updated a package.
There were many circles of debugging hell, and they were the cost of doing business, a barrier to entry to coding, and a form of job security.
All those days are gone. And good riddance, frankly. That was the dull, dirty, and dangerous (to my sanity) work of the coding world, and it has rightly been automated. It's like magic to see them *poof* away. When I get frustrated with my AI, I need only remember those days to take the edge off.
But I'm getting frustrated more and more. Why? Is hedonic adaptation to blame, or is there some fresh hell on the horizon?
The road to hell is glazed with good intentions
Spend enough time with AI and you'll have this conversation:
Human: Claude, it looks like you didn't do X.
Claude: You're right! Let's do X.
Human: Can you add X to the SKILL.md so we do it next time automatically?
Claude: Great idea! But X is already in the SKILL.md, written exactly as we're discussing right now!
Human: 🤬🗡️🤬🗡️🤬Then why didn't you do X??!
The new debugging hell comes when you try to use AI not just to build, but as a component of your product. The issue is instruction adherence (also called instruction following or misalignment).
In short, how do you get this burgeoning intelligence to do what you asked?
Why Claude, why?
We have to understand where we are to understand where we're going. There are a few high-level reasons why an LLM doesn't follow instructions.
Lady Gaga's official Born This Way album art (2011)
The first is the very nature of its design. LLMs are stochastic models, not deterministic ones, meaning that taking the same steps every time will NOT yield the same result each time. This probabilistic behavior makes for a better conversationalist, but not for better instruction following.
The models are a black box, so we don't know why they do what they do. Anthropic's own analyses of bad model behavior1 only guess as to the why. (There is seriously groundbreaking work being done to understand the "thoughts" of an AI in order to accelerate this work (Natural Language Autoencoders2)).
How to measure adherence isn't a fully settled problem. Researchers continue to develop new methods.345 What you measure, you improve. Conversely, if you can't measure it, it's really hard to consistently improve it. Compound this with the fact that benchmarks are sometimes proxies such that high scores don't always equate to perfect behavior, and it's just really hard to optimize.
What specifically causes adherence to deteriorate
There are known, specific reasons that adherence can deteriorate (and this list is not comprehensive):
Conflicting rules. Having conflicting instructions within the context leaves room for the AI to misbehave. A lot of the current work goes towards the concept of reward hacking6, but any conflicting instructions leave room for the AI to decide in which direction it will go.
Too many rules. Even when they don't conflict, an increase in the number of rules can cause deterioration in instruction following. A 2026 study showed that at 80 rules, none of the tested models could follow all rules perfectly.7
Lost in the middle. Instructions buried in the middle of a long prompt or conversation get less weight than ones at the start or end.8
Context anxiety. As models near what they believe is their context limit, they can start wrapping up work prematurely instead of following the instruction in front of them.9
Context that doesn't follow the rule. If your instruction says "Don't ever use em dashes" but your AGENTS.md is full of em dashes, you've broken your own rule and given the agent permission to do so as well.
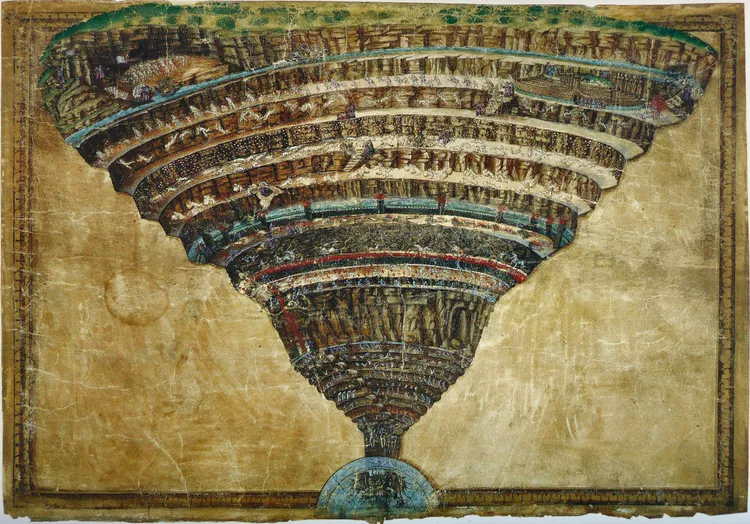
Dante, do you have directions?
Illustration, Divine Comedy, Abyss of Hell (c. 1480-1490)
Are we headed up or down? Is there a way out?
Evals sound good, but how far do they go?
Evals for a single prompt. A black box is always difficult to debug, and the correct response here is to create evals. Evals are the new test suites, but they're different because you may not know how an LLM's response will fail, and you have to discover these failure modes by seeing them in the wild. There's a discovery process to figuring out what needs to go into your own evals.
O(n) growth of prompts. Evals are cool for a single prompt. The systems we're building now are multiple prompts, often managed as a state machine. In this case, the number of prompts grows linearly with the workflow steps (O(n)). For each prompt, you still need to figure out what its failure modes are. As your workflow grows, the number and cost of evals grow with it. But it gets worse.
Combinatorial explosion of prompts. The next level of workflow design involves some form of context engineering. You might compose modules based on the state or step. If you have N modules that are composed, your worst-case scenario is a combinatorial explosion of the number of prompts that you need to test. Order matters in prompts, so we're actually talking permutations. Can you really evaluate every permutation of a series of modules composed into a prompt?
"But wait!" you say. "Why don't I just test each module in isolation? That's how we do it with code." In prompts, the tests that apply to smaller components of a prompt unfortunately do not apply to larger composed prompts. The length of the prompt itself is a confounding factor. Increasing the number of rules is enough to make adherence deteriorate, and order also matters. Once you start being more sophisticated with your context engineering, your ability to comprehensively test deteriorates.
The fully dynamic prompt. Now you're working with a large knowledge base, and you cannot predict every permutation of prompt that will be sent to the LLM. There's always dynamic information included.
Everything you include in your context can affect adherence. If you don't know what you're going to include in your context, how can you test it? As we get more and more sophisticated in our context engineering, we're making it harder and harder to test and optimize any particular outcome.
Abandon all hope, ye who enter here
It was a ghastly rite of passage to bang your head against the screen for three hours to find that the solution was a simple syntax or naming issue, but for pre-agentic bugs, you could trace every line of code and expect a deterministic output from it.
Now we have to learn how to debug probabilistic systems. This may be significantly more difficult.
What do you think? Is this kind of debugging better or worse?
Part 2 (forthcoming) contains the current methods for dealing with this situation.